

 LinkedIn
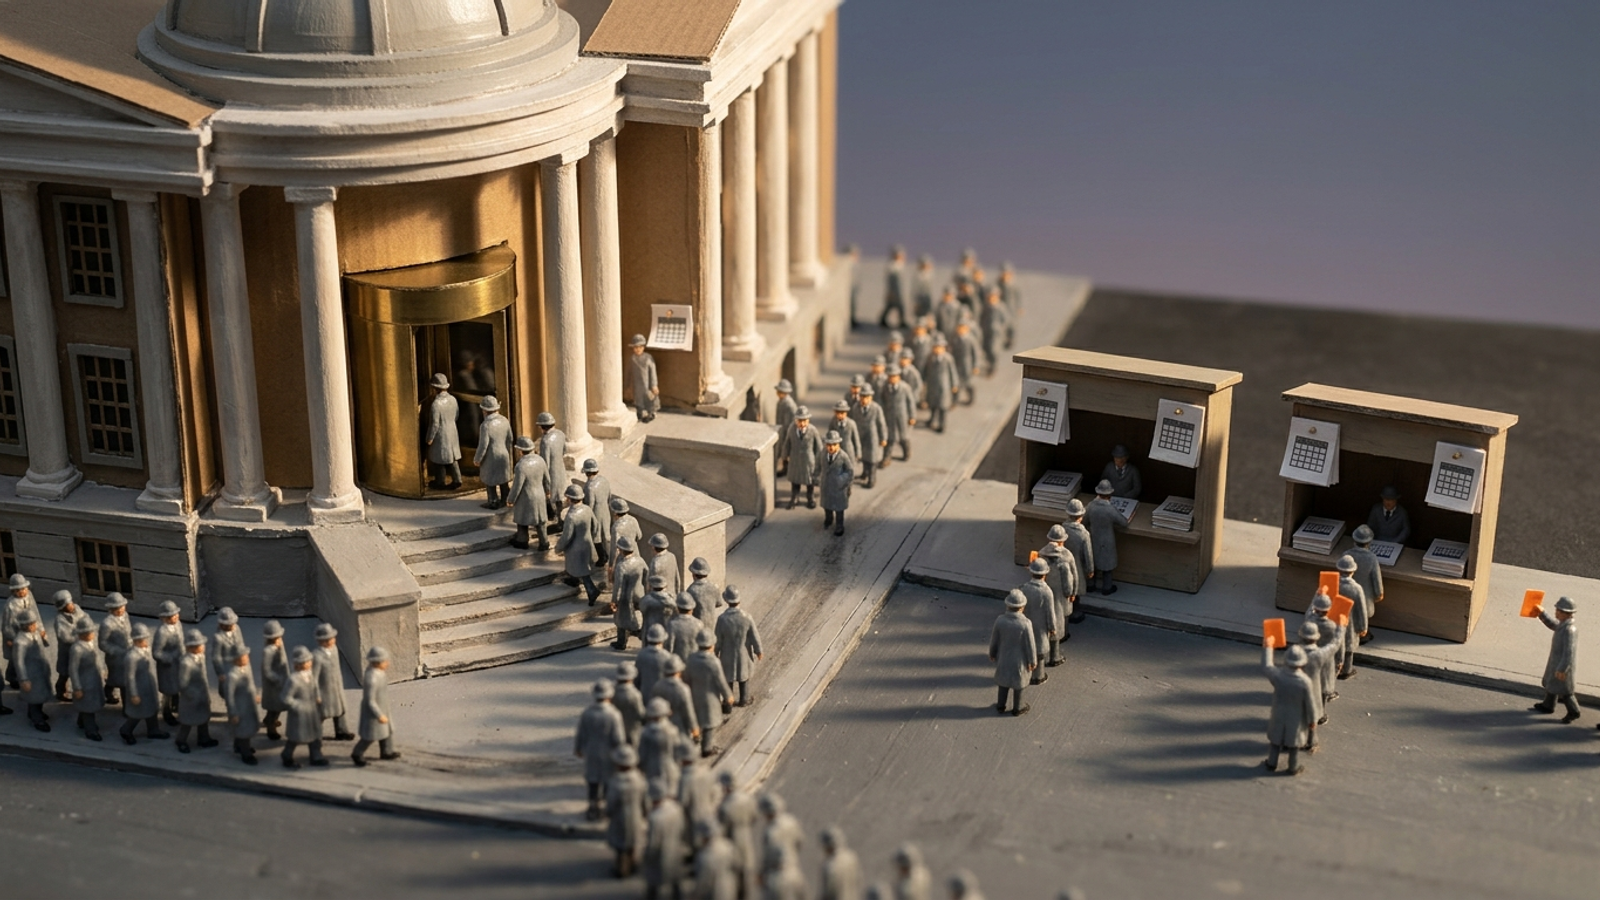
AI bots fetched two of our hub pages hundreds of times in a month. Neither page fed a single live answer. I used to treat a spike in bot fetches the way I treated a spike in Google Ads impressions: more looked like more. Then I checked the metric that mattered.
Over one 30-day window, groas’s edge logs showed 234 and 251 verified fetches for two category and index pages, respectively. Each recorded zero live-answer fetches. In the same window, /post/google-ads-updates-2026 recorded 467 live-answer hits, and /post/every-google-ads-change-that-matters-in recorded 284. The pages we thought were doing the broad visibility work were being read, but they were not feeding answers. Two dated articles were.
This is the postmortem: what we assumed, the first warning in the logs, the call we got wrong, and the rule I use now. It is also a reminder that crawled and used in an answer are different events. Confuse them and a healthy-looking chart can keep you comfortable while the answer goes to another page.
The setup: we counted visits to the library
Our category and index pages were built to help people browse. They gathered topics, linked to articles, and gave crawlers paths into the site. If I had looked only at verified bot activity, I would have called them healthy. The fetch counts were right there, and they were not small.
A verified fetch means our edge confirmed the bot was who it claimed to be, such as ChatGPT, Claude, or Gemini, when it requested the page. A live-answer fetch means the request happened while an assistant was building an answer to a prompt. Verification tells us who came through the door. The live-answer distinction tells us whether the visit was part of answering a question. Neither, on its own, proves that the page appeared as a visible citation in the final response.
We let the first number stand in for the second. It is an easy mistake when you are accustomed to reporting activity: the chart rises, the URL is getting attention, and everyone moves on to the next meeting. I have made the equivalent mistake in paid search. Impression share can look fine while CPA gets worse. You do not fix that by admiring the impressions more carefully.
Our working assumption was that frequent verified crawling meant useful AI visibility. We should have tested whether those same pages were feeding live answers. That was the check the setup needed before anyone called the hubs a win.
The first sign: two zeroes beside hundreds of fetches
The path-level view broke the story. One hub page had 234 verified fetches; the other had 251. Both had zero live-answer fetches. Not a weak conversion rate. Zero. The two dated posts, meanwhile, logged 467 and 284 live-answer hits.
The distinction matters because a bot can retrieve a page without using it to answer the prompt in front of it. In a study of 548,534 retrieved pages across 15,000 prompts, only 15% were ever cited. That study measures citations, not our live-answer fetches, but it describes the same trap in a different measurement system: being read is not the finish line.
There was another warning in the raw traffic. Hits that looked like AI interest included training crawlers, scrapers wearing bot user agents, and repeat conditional requests. Those do not belong in the same column as verified requests. I used to tell clients that bot traffic in server logs meant demand. I was wrong; first you have to establish who made the request, then ask what happened after it.
One server-log case showed PerplexityBot reaching 60 distinct paths, including new posts within 14 to 20 hours. Yet a fixed 36-answer citation test stayed at 3 of 36. Faster discovery did not move that answer test. Our own paths were sending a similarly uncomfortable signal: the fetches were real, but the live-answer use was not there for the hubs.
That was the moment to stop calling crawl volume visibility. We did not stop soon enough.
The wrong call: we defended pages built to browse
Our hubs listed a dozen topics and pointed readers toward other pages. That is a job. It just was not the job we were measuring them against. Someone browsing a site may want a map of the library. An assistant assembling an answer needs material that responds to the question in one place, with enough specifics to use without stitching together three URLs.
The two posts did that better. The updates article had a date in its title, a dated change log in the body, and numbers an assistant could repeat. The every-change article approached the subject from the other side: what changed, when, and what to do about it. Neither tried to serve as a category index. Each gave a particular question a more complete answer.
That does not mean a date or a table magically earns a citation. It means the page has to make its answer available. In one study of 8,000 citations across 57 commercial queries, 82.5% pointed to highly specific nested content rather than homepages or high-level category pages. That finding did not diagnose our site for us. Our path-level logs did. It did, however, make the failure mode familiar.
Our most-fetched pages were the least suited to answering a specific question. We kept defending them as though internal links and broad coverage settled the matter. They may have earned their place as navigation; they had not earned the live-answer visibility we credited to them.
We made a second wrong call in the report. Our mention tracker showed flat or rising brand visibility, which sounded reassuring. But a brand mention and a URL citation are separate events; either can occur without the other. A mention score could not tell us which of our pages fed an answer. A crawl count could not tell us whether a page was cited. We had three different questions and kept reaching for one blended sense of progress.
The damage: the chart stayed pleasant while answers went elsewhere
The cost of this mistake was quiet. For weeks, we reported healthy bot activity while the hub pages recorded no live-answer fetches. The chart did not force a hard conversation because the number on it was genuinely going up. It was simply the wrong number for the conclusion we wanted to draw.
Meanwhile, live answers to buyer prompts cited dated posts from other sites that had done the boring work: one question, a date, and specifics in one place. We had evidence on our own site that this shape could feed answers. Our two dated posts logged 467 and 284 live-answer hits. We also had evidence that our hub template was not doing the same job. The 234 and 251 verified fetches bought those pages no live-answer hits in the window we examined.
This is where I want to be careful about language. A live-answer fetch is not automatically a visible citation. To know which URL the user saw cited, you have to inspect the answer. But zero live-answer fetches beside hundreds of verified fetches is already a serious warning. The pages were attracting the bots we could verify without appearing in the live-answer fetch column we were watching. Calling that visibility would have hidden the problem before we even checked citations.
There is a broader version of the same failure: a bot can fetch a site repeatedly without recommending it. The visit is evidence of access, not endorsement. We were measuring visits to our building while the conversation we cared about could happen across the street.
The practical damage was the time we spent protecting the wrong template. Every week we treated those hub fetches as good news was a week we did not ask why the pages failed the live-answer check.
The fix: make the answer page, then measure the answer
The fix was not to publish more pages indiscriminately. We mapped the buyer prompts we wanted to win to URLs that could answer them on their own. For the pages we rewrote, the assignment became specific: put the date up top, define terms plainly, place numbers where they are easy to read, and give the prompt a short summary block that does not depend on another page for its meaning.
Field work on citation-friendly content makes a similar distinction: comparison content gets cited where category descriptions do not. It recommends unglamorous features such as HTML tables, buyer-phrased FAQs, and a factual summary near the top. Our zero-live-answer hubs had none of that. Our two successful posts had much of the underlying specificity, though not because we designed them from the start around this scoreboard.
The question also affects what a useful answer page looks like. In the retrieval-and-citation study, product-discovery and how-to prompts were cited at 18.3% and 16.9%, compared with 11.3% for validation prompts. Those figures do not predict what any one rewrite will earn. They are a useful warning against treating every buyer prompt as the same assignment. Write the page for the question rather than forcing every question through a category template.
We changed the scoreboard at the same time. Verified bot fetches still matter: if the bot never reaches a page, it cannot use it. But live-answer fetches by path now sit beside verified fetches, not underneath a broad visibility label. Unverified hits, training crawlers, and conditional re-requests stay separate so they cannot flatter the chart. When we inspect answers, we record mentions and cited URLs separately, too.
I check those columns the way I used to check search terms: which URL was involved in a live ChatGPT or Claude answer, and which URL merely got read? The first may deserve more investment. The second needs a closer look at the prompt and the page before anyone celebrates its traffic.
The same check, without a flattering visibility score
You do not need our site’s exact mix of hubs and dated articles to run the check. You need a repeatable set of buyer questions, your request data, and the discipline to keep crawling separate from answer evidence. The standard advice to test buyer prompts and log brand mentions is a start, but it leaves open the question our logs exposed: which URL fed the live answer, and which page merely got crawled?
Say you sell Google Ads management. “Best agency” is not much of a prompt set. Questions about structuring a SaaS campaign, judging CPA at $20,000 a month, or whether Performance Max cannibalizes brand search give you something closer to the decisions a buyer is trying to make. Use the same prompts across the engines you care about, and save the full answers rather than a yes-or-no record of whether your brand appeared.
- Pull verified bot fetches by path from your edge or server logs for the last 30 days. Keep unverified hits, training crawlers, and repeat conditional requests out of that count.
- Run 30 buyer prompts in ChatGPT, Claude, Gemini, and Perplexity. For each response, record the full answer, whether the brand was mentioned, whether it was cited, and the exact URL shown if there is a citation.
- Put the evidence side by side. For each URL, compare verified fetches, any live-answer fetches your logs identify, and citations you observed in the saved answers. Do not treat one column as proof of another. Pages with heavy verified fetching and zero live-answer fetching have earned an investigation, not a visibility badge.
- Rewrite one weak page first. Give it a single question to answer, a current date where the subject calls for one, readable numbers, and a short stand-alone summary. The fuller page-writing approach is in how to get cited in ChatGPT and Perplexity.
A tool helps only if it preserves those distinctions. A blended mention score may tell you that the brand appeared in some answers; it will not tell you that a particular hub drew hundreds of fetches without feeding a live answer. Retrieval can also look impressive at scale without producing citations: in the cited 1.4-million-prompt analysis, Reddit URLs were retrieved broadly but cited in only 1.93% of cases. A reading list that never quotes you is not the outcome you were trying to buy.
My rule now is one line, and I apply it to this site too: no page gets to claim live-answer visibility on crawl counts alone. If it is fetched hundreds of times and feeds zero live answers, I investigate the question it is supposed to answer and rewrite the page instead of celebrating the fetches. The logs can tell us who read it. The answer check tells us whether that reading mattered.